SimpleBench‑X: The Community‑Driven LLM Evaluation Framework Unifying Open‑Weight Benchmarks
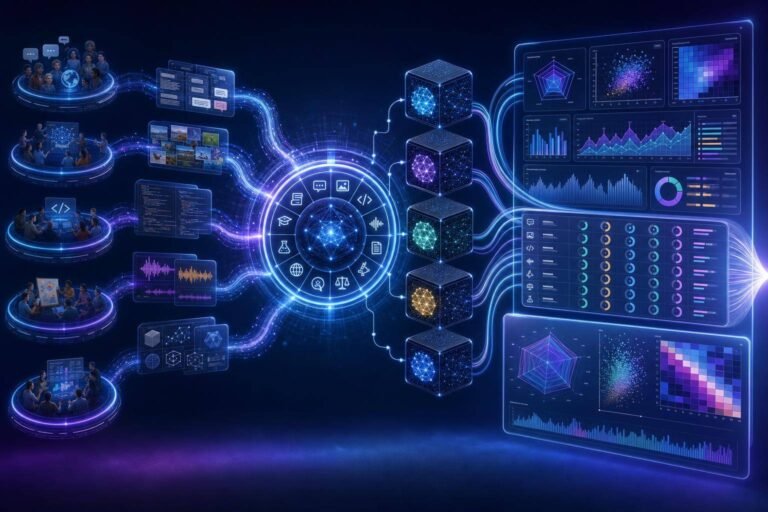
Fragmented benchmarks and inconsistent scoring have made it difficult to know which large language model will actually perform best for your use case. Vendor‑controlled leaderboards raise another challenge: they often prioritize favorable metrics over transparent, reproducible science. The Open LLM Consortium’s launch of SimpleBench‑X is a timely reset. It’s an extensible, community‑driven LLM evaluation framework…